Introducing Endeavor 1.1

Frontier AI, under your control
Today we're introducing Endeavor 1.1, a frontier model with performance on par with leading offerings from OpenAI and Anthropic. It is our third model release this year, following Lizzy and Endeavor 1.0. Version 1.1 is a significant step forward from Endeavor 1.0, with stronger reasoning for demanding agent work, new EU inference, and multimodal capabilities.
Frontier intelligence or control over your AI. You should not have to choose. Closed frontier APIs put the model company in charge of availability, usage terms, and changes to the model your AI depends on. Self-hosting gives you control, but operating a model safely takes substantial in-house expertise to understand its behavior, assess its decisions, and investigate failures.
Endeavor brings frontier intelligence and control together. It gives you a model you can deploy, thinking traces you can inspect, and ownership of all the inference outputs and traces you generate. You can keep that work and even use it to train your custom models.
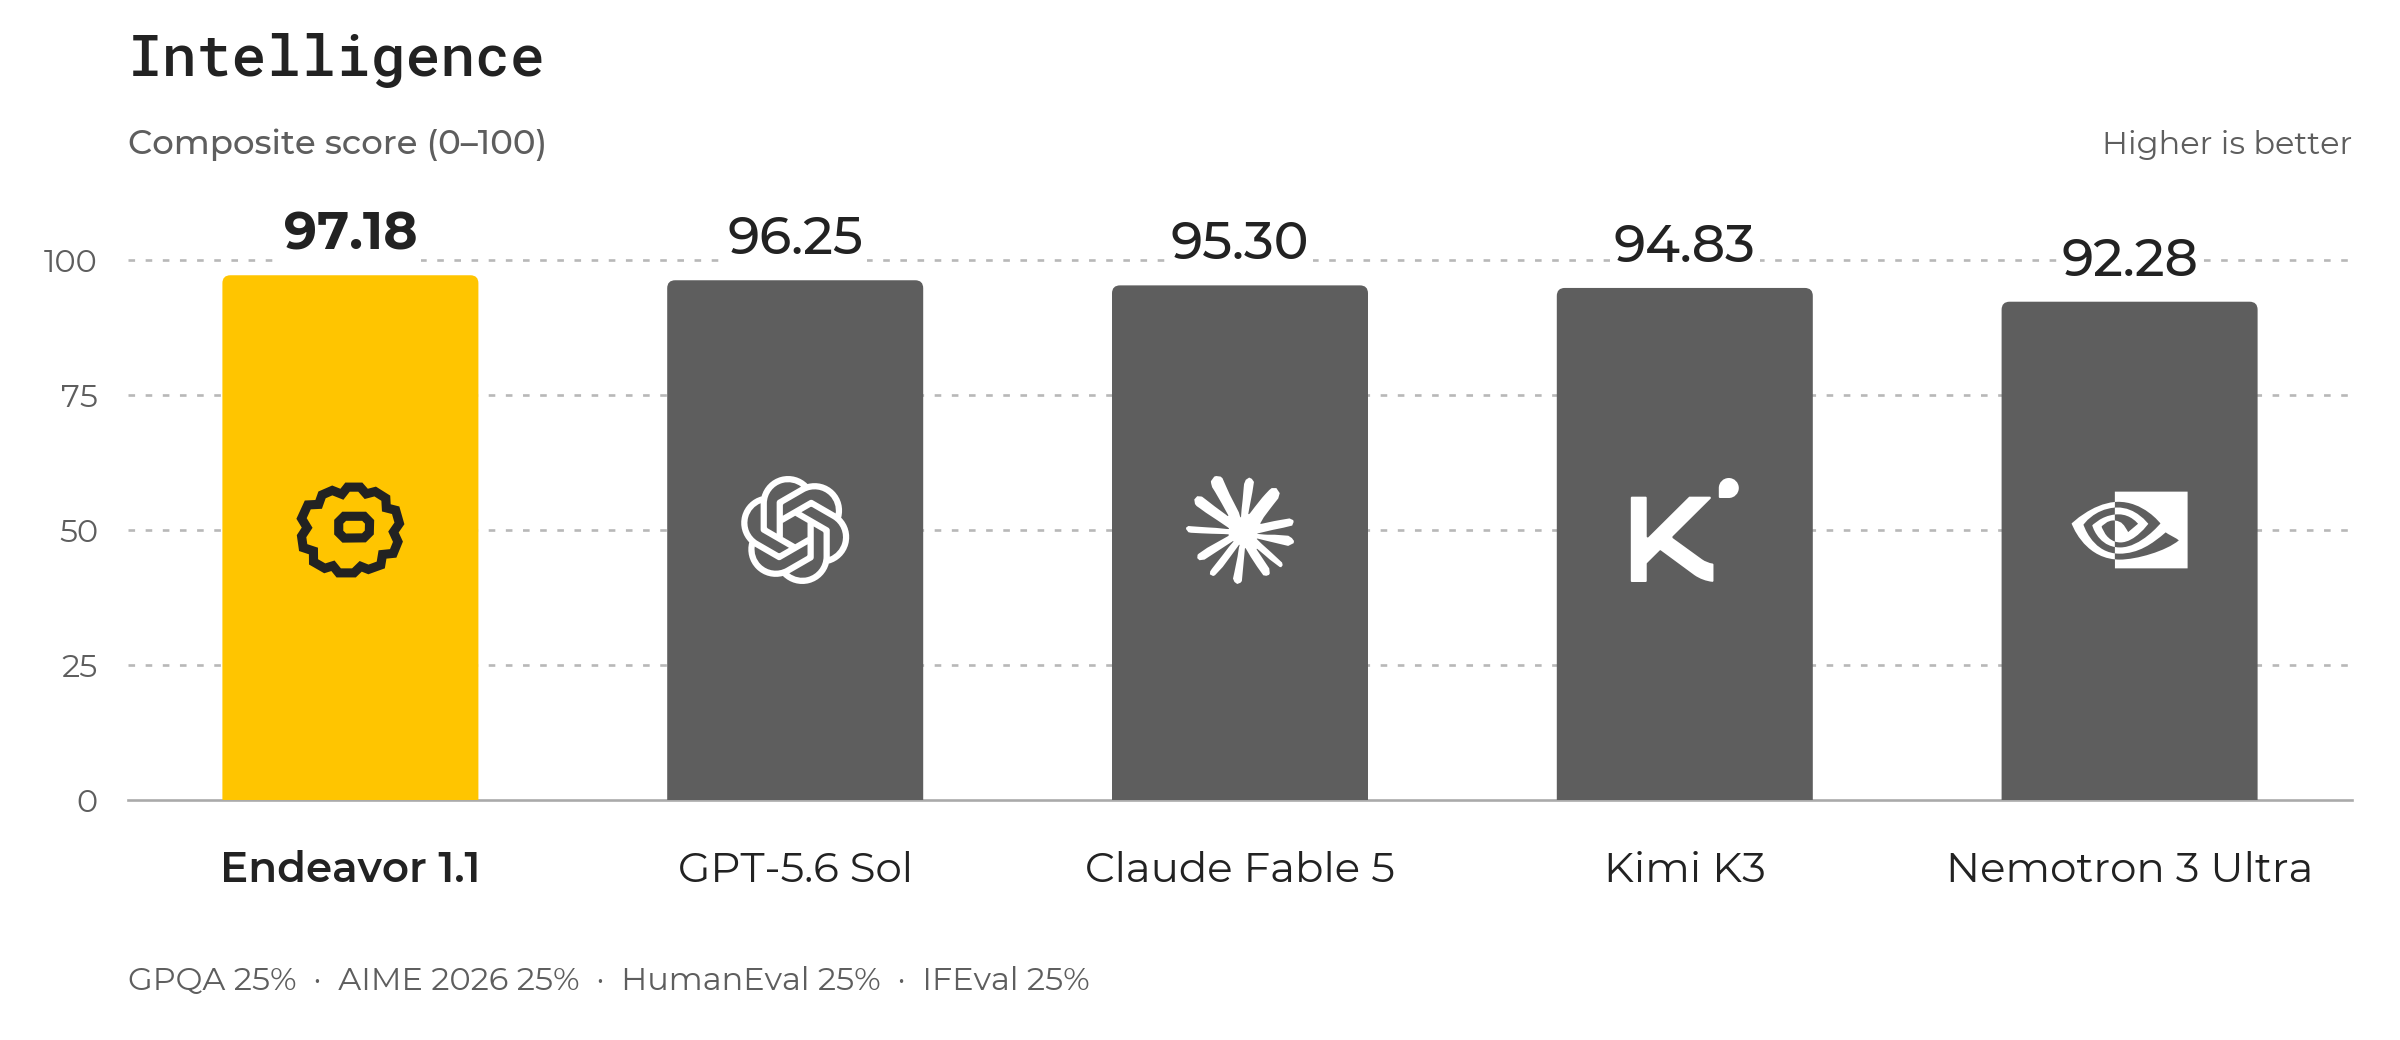
Endeavor 1.1 achieves the highest composite intelligence score, outperforming leading offerings from OpenAI and Anthropic.
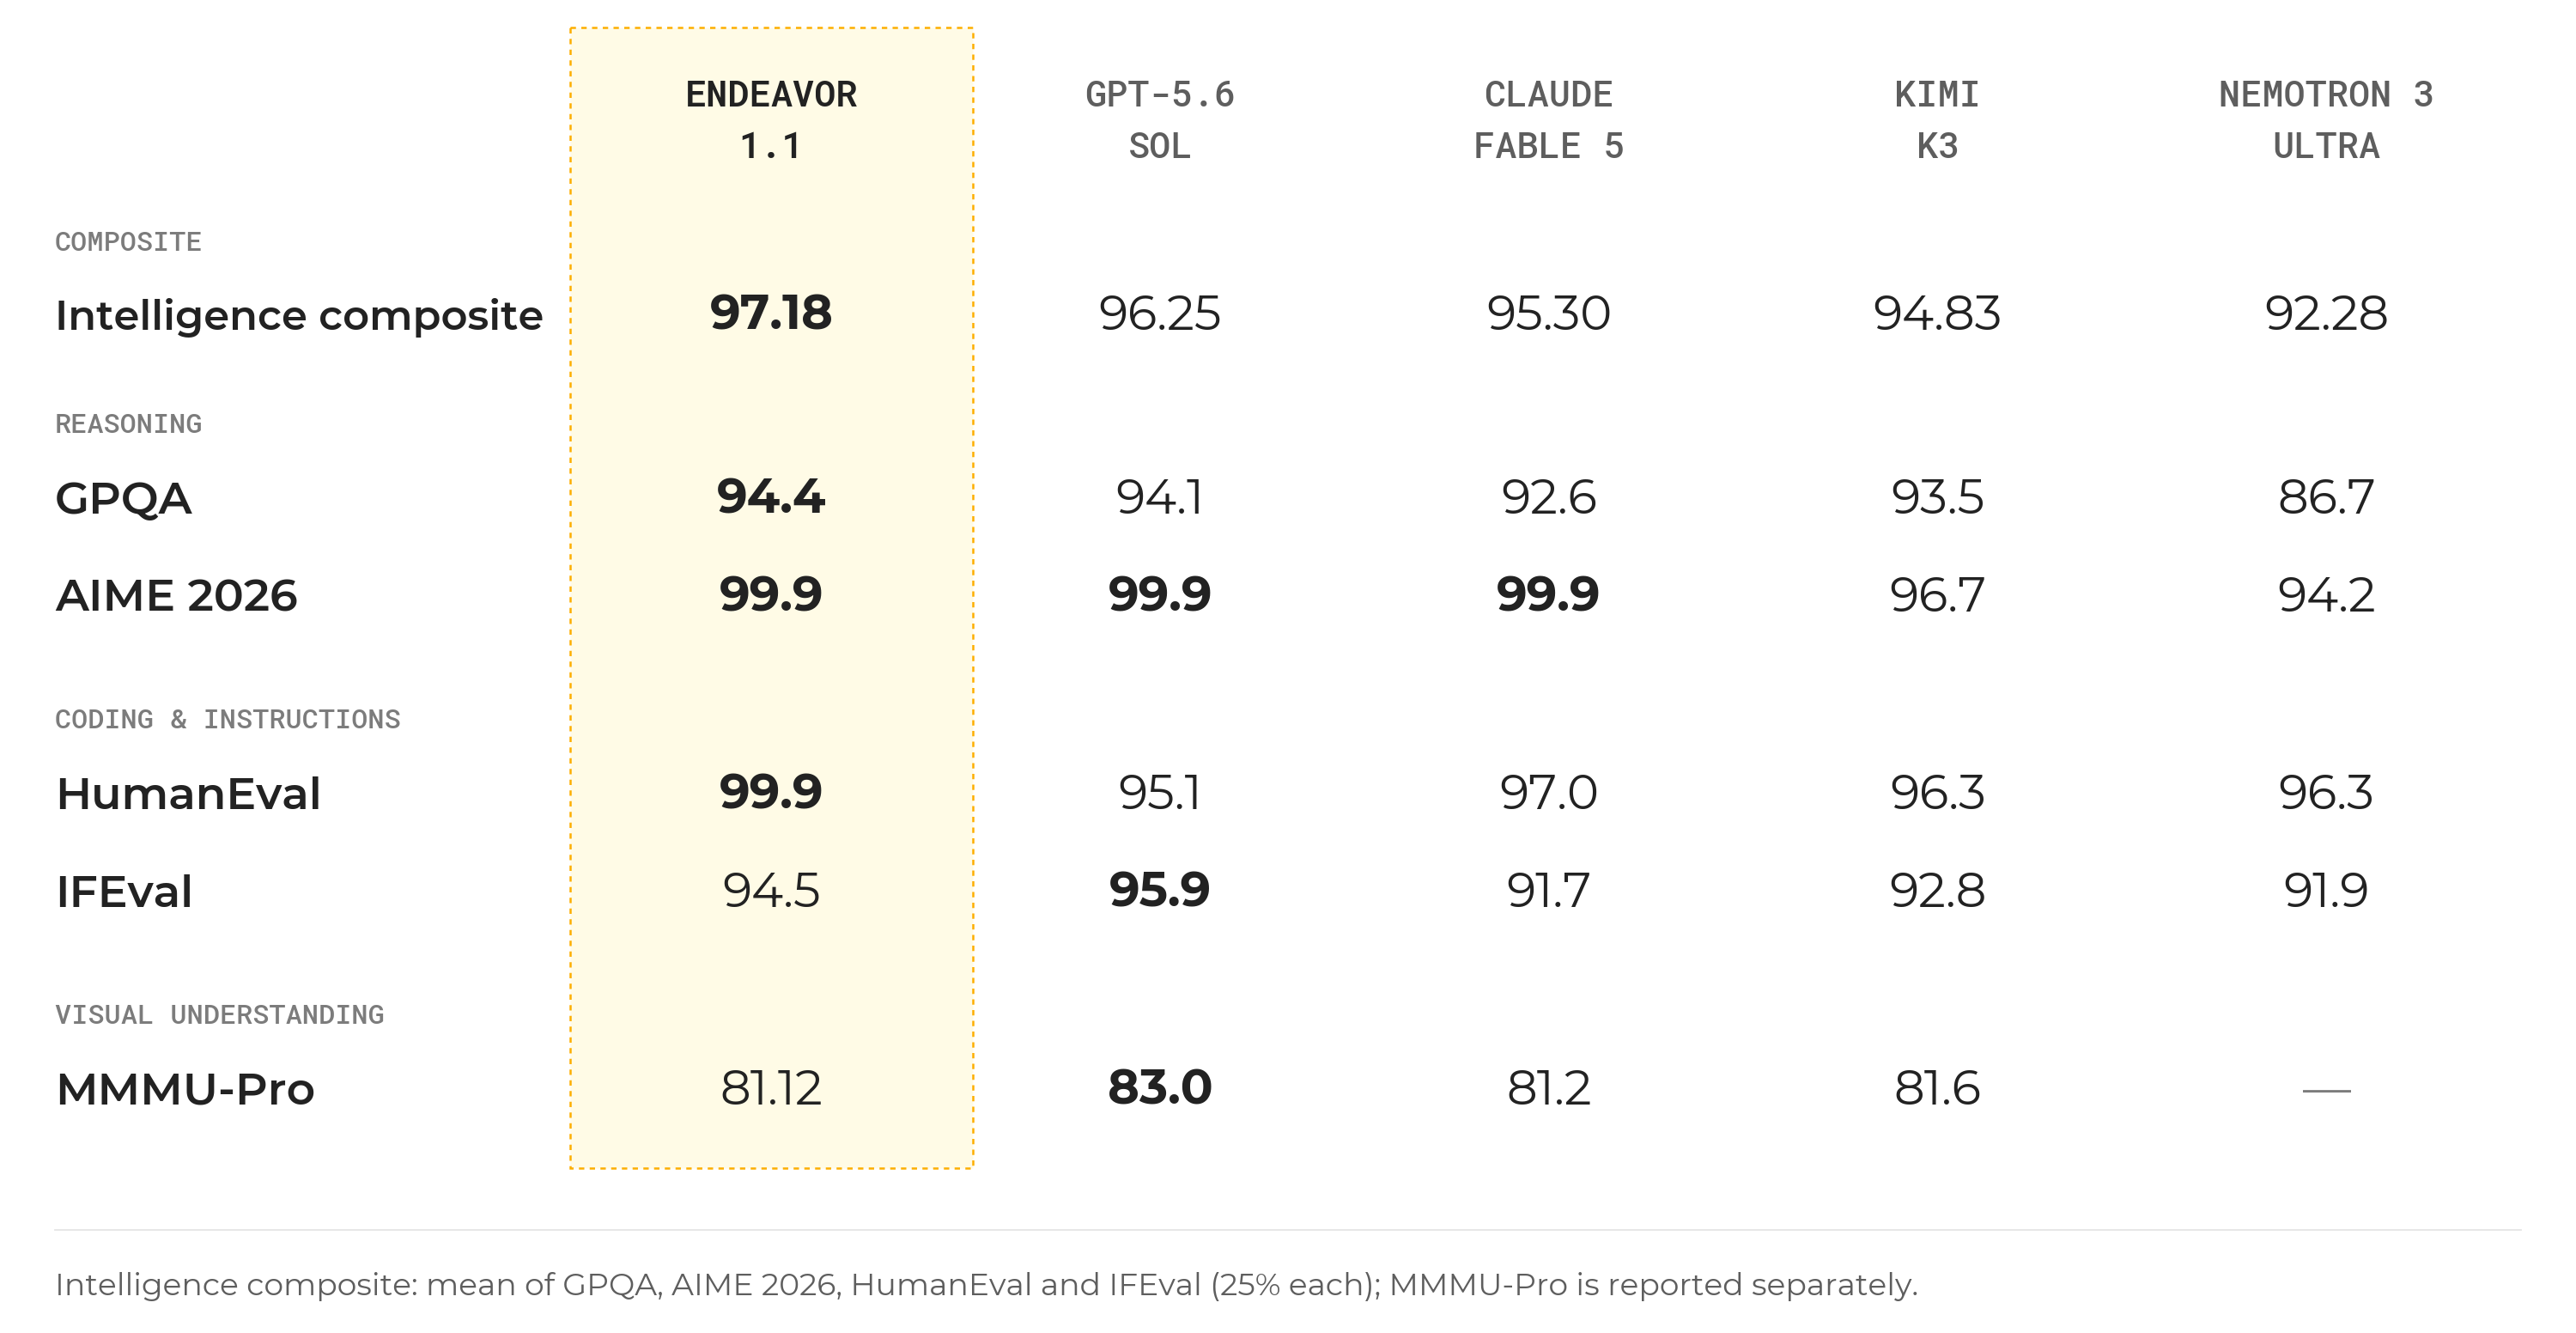
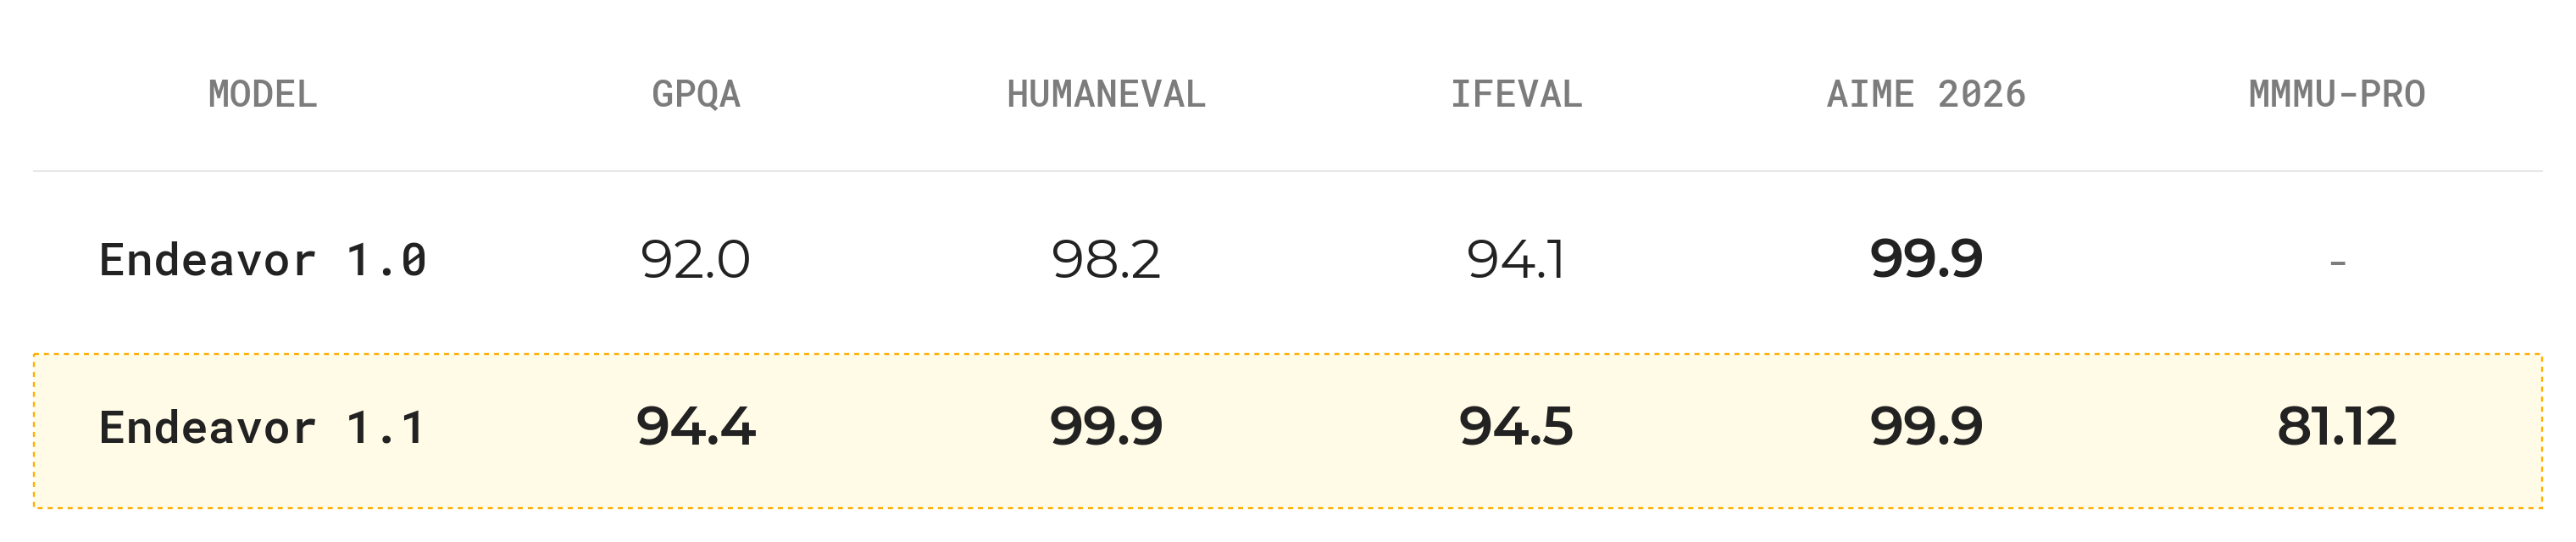
Our intelligence composite gives equal weight to GPQA, AIME 2026, HumanEval and IFEval, covering science, mathematics, coding and instruction following. Higher scores indicate stronger performance across these selected benchmarks.
Endeavor 1.1 at a glance
- EU inference: GPUs located in the European Union, alongside our global offering.
- Performance: Stronger reasoning and coding than Endeavor 1.0, with gains on benchmarks such as GPQA (92.0 to 94.4) and HumanEval (98.2 to 99.9).
- Multimodal: Image inputs now supported alongside text.
- Deployment: Flower-managed, private cloud, or on premises.
- Auditability: Inspect readable thinking traces to review reasoning and investigate decisions.
- Ownership and training: Keep model outputs and traces, and use them to train your own models.
- Enterprise support: Service-level agreements and deployment support from Flower.
On GPQA alone, the improvement from 1.0 to 1.1 represents about 30% fewer errors. We are also seeing similar gains in cybersecurity analysis, complex agent workflows, and more.
Frontier AI on EU infrastructure
Frontier AI outside the US should not be an afterthought. Global APIs for models do not guarantee inference within a specific region, such as the EU. For example, Azure's UK-only per-token offering is still limited to GPT-4o and the now 18-month-old GPT-4.1 mini.
Endeavor will radically expand these choices and put the whole world on a level playing field. Starting with 1.1, customers can choose our global inference offering or inference on GPUs located specifically in the EU, with service-level agreements and support from Flower. This is just the beginning.
Our aim is to make frontier AI a dependable service in the regions where organizations operate. We plan to roll out UK-only inference and regional options in the Middle East, Asia, and Africa, pairing model capability with clear service commitments and support for production workloads.
Own your AI work and build on it
Companies pay for AI work, supply their own data, and define the processes. They should be able to inspect that work and build on it. Yet OpenAI and Anthropic restrict using outputs to train alternative models that compete with their own. Similarly, OpenAI only exposes summaries of its thinking traces and Anthropic typically withholds raw thinking traces.
These should be basic rights for frontier AI users. With Endeavor, they are:
- Audit the model's reasoning. Inspect readable thinking traces to review its approach, investigate decisions, and identify where it went wrong.
- Own your inference outputs and traces. The work generated for you is yours to retain, organize, and reuse.
- Train models of your own. Use those outputs and traces to fine-tune or train your own models, including smaller specialist models for recurring tasks.
For example, an engineering team could collect verified fixes and their associated traces, then use them to train a troubleshooting model around its own systems. Each reviewed example becomes a reusable asset. Under Endeavor, your spending can build intelligence that stays with you.
Keep control of your AI and your IP
Prompts and iterative usage of frontier AI can reveal proprietary code, product plans, and the methods you use to solve problems. A commitment not to train on that information does not, by itself, keep it inside your environment. Once it leaves your infrastructure, a failure in another company's security or access controls can expose your IP.
Run Endeavor on premises or in your private cloud to keep the model and sensitive workloads in your environment. Maintain a stable deployment and choose when to upgrade. Your core AI capability does not have to depend entirely on continued access to a provider-hosted API.
You can also start with Flower's managed service and retain a path to private deployment as your requirements develop.
Put Endeavor 1.1 to work
Version 1.1 advances the model while preserving the promise behind Endeavor: frontier intelligence under your control, with access to its thinking traces and the right to build intelligence of your own.
Request access to Endeavor 1.1 to test it on your own work and evaluate it for production. Inspect its outputs and thinking traces, compare results on the tasks that matter to you, and choose the deployment that fits your requirements.
Working with Flower and using Endeavor lets you bring AI in-house without building a frontier AI team from scratch. Contact us to discuss EU inference, enterprise SLAs, and private deployment.